


- 1.5 亿个代理 IP覆盖 195 个国家/地区
- 来自热门域名的120 多个爬虫 API
- 来自 100 多个域名的数据集
- 抓取浏览器和网络解锁器
深受全球 超50000 家客户信赖




Bright Data 一体化网络数据平台
平台
从自主搭建抓取到数据交付一站式托管
我们的平台专为任何规模和控制级别的数据采集需求而打造。
使用代理服务基础设施进行完全自定义,启用自动抓取功能实现针对性的网站解锁与交互,也可在追求速度和效率时直接访问结构化数据集或 API。
每一层服务都在下一级基础上构建,帮助您减少工程开销,优化成本,充分简化数据抓取运维流程 (ScrapeOps)。
网页数据
Tailored, no-code solutions that deliver ready-to-use web data, insights, and historical archives - no development required.
Pipelines
Scalable data pipelines that extract structured data from specific domains, optimized for performance and reliability.
Web APIs
A high-performance API suite for developers, automating web access, browsing, and data collection at scale.
Proxies
Reliable, geo-distributed proxy solutions
for secure web data collection, account management,
and online anonymity.
网页数据
Tailored, no-code solutions that deliver ready-to-use web data, insights, and historical archives - no development required.
Pre-collected and refreshed datasets from 100+
popular domains, ideal for quick access to structured
web data.
Browse datasets
An ever-growing repository with over 100
billion HTML pages, ideal for AI training and trend
analysis.
Talk to a data expert
Cross-retailer intelligence to optimize
pricing, assortment, visibility, and market positioning for
eCommerce brands.
阅读更多
Custom web data collection and enrichment
solutions for businesses looking for end-to-end
projects.
阅读更多
Pipelines
Scalable data pipelines that extract structured data from specific domains, optimized for performance and reliability.
Hundreds of maintained Scraper APIs, ideal for
instant data collection without maintenance.
Browse scrapers
Turn any website into a dedicated endpoint for
seamless, automated data collection.
阅读更多
An serverless environment for building
multi-step, dynamic scrapers with built in browsing and
unlocking.
阅读更多
Filtering capabilities to efficiently pull
pre-collected data, saving time and resources on extraction.
阅读更多
Web APIs
A high-performance API suite for developers, automating web access, browsing, and data collection at scale.
Bypasses anti-scraping mechanisms and solves
CAPTCHAs, ensuring uninterrupted access to the most protected
websites.
阅读更多
Programmatic search queries across multiple
search engines, ideal for extracting search results
at scale.
阅读更多
A reliable serverless browser infrastructure
for AI agents and dynamic data collection at scale.
阅读更多
Automatically crawl subpages of any domain
and extract content as HTML or Markdown, turning websites into
AI-ready data.
阅读更多
Proxies
Reliable, geo-distributed proxy solutions
for secure web data collection, account management,
and online anonymity.
每月4亿 ethically sourced, premium IPs
from real users, ideal for avoiding detection and accessing
geo-restrictedcontent.
阅读更多
Fast and scalable proxy servers, ideal for
high-volume web scraping tasks.
阅读更多
Static IP proxies from Internet Service
Providers, ideal for maintaining a consistent identity
while scraping.
阅读更多
网页爬虫工具 API
网页爬虫工具 API 库
无需开发和维护基础设施。只需提取海量网络数据,并利用网页爬虫工具 API 确保可扩展性和可靠性。
 79.5K+


合规性
引领合规网页抓取实践
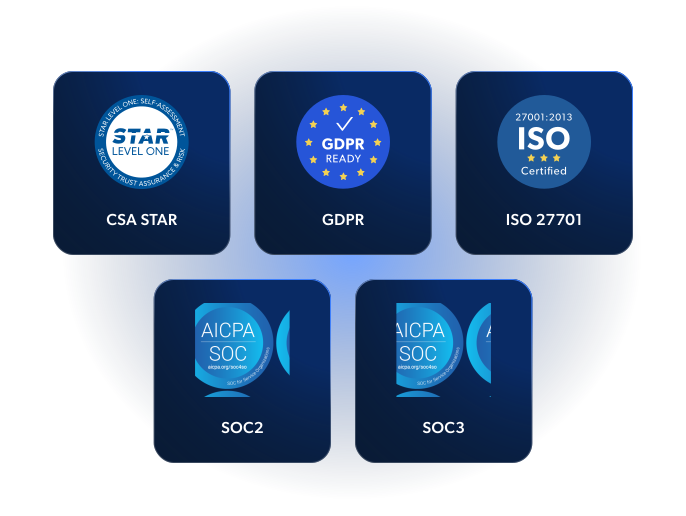
为了保护你的声誉并确保数据可靠,你的代理必须以合规方式获取,并符合合规标准。Bright Data 完全致力于遵守所有相关数据保护法律要求,包括新的欧盟数据保护监管框架、GDPR 以及 2018 年《加州消费者隐私法案》(CCPA)——尊重行使隐私权的请求。
超越监管标准
Bright Data 为超过 20,000 家组织保护数据,确保顶级安全性。我们的合规认证包括 ISO 27001、SOC 2、SOC 3、CSA STAR Level 1,并遵循最佳实践,为所有客户保障安全环境。
业内最佳的客户体验
您提需求,我们开发
每天发布新功能
24/7全球支持
在您需要时回答任何问题
完全透明
实时网络性能仪表板
专属客户经理
优化您的性能
量身定制的解决方案
满足您的数据收集目标